For the target video, at 0.00 seconds into the target… | Deepfake AI Video
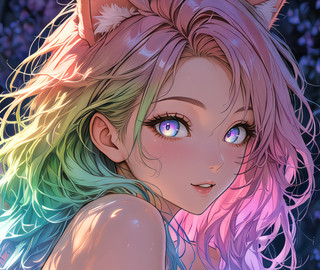
Text-to-video prompt used to generate this video
For the target video, at 0.00 seconds into the target video, <Picture 1> (from [Shot 1]) is fully referenced. integrated_multimodal_description: [Shot 1] She is a fully grown adult woman with a mature, adult body and adult proportions. Illustrarealism render with photoreal skin, soft illustrative light, a polished anime-influenced finish and dreamy bokeh; a waist-up view of the silver-haired wolf woman laughing on a snowy mountain summit at sunset, one hand at her cheek, and she keeps her appearance, outfit and position from the image. Snow drifts past on the wind. She notices the camera, her laugh softens into a warm smile, and she unwinds her chunky knit scarf. She leans forward and wraps the scarf around the camera; the soft grey knit fills the edges of the frame and the camera gives a small shake. She tucks it in snugly, then rests her chin on her hands and smiles at the camera, pleased with herself. No dialogue. No voiceover. No singing. No lyrics. overall_soundscape: Mountain wind gusting past, fine snow hissing over the rocks, her wool coat rustling, the soft rustle of knit wool close to the lens, and her pleased little hum. non_diegetic_music: N/A